Dense vs. MoE Models: Active Parameters, Throughput, and When to Choose Each
NVIDIA’s Sophia Abbassi explains MoE versus dense tradeoffs with Nemotron 3.5 Lightning—30B total, 3B active—where memory stays high but compute per token drops.
Desk
NVIDIA hardware, software, and developer news.

NVIDIA’s Sophia Abbassi explains MoE versus dense tradeoffs with Nemotron 3.5 Lightning—30B total, 3B active—where memory stays high but compute per token drops.

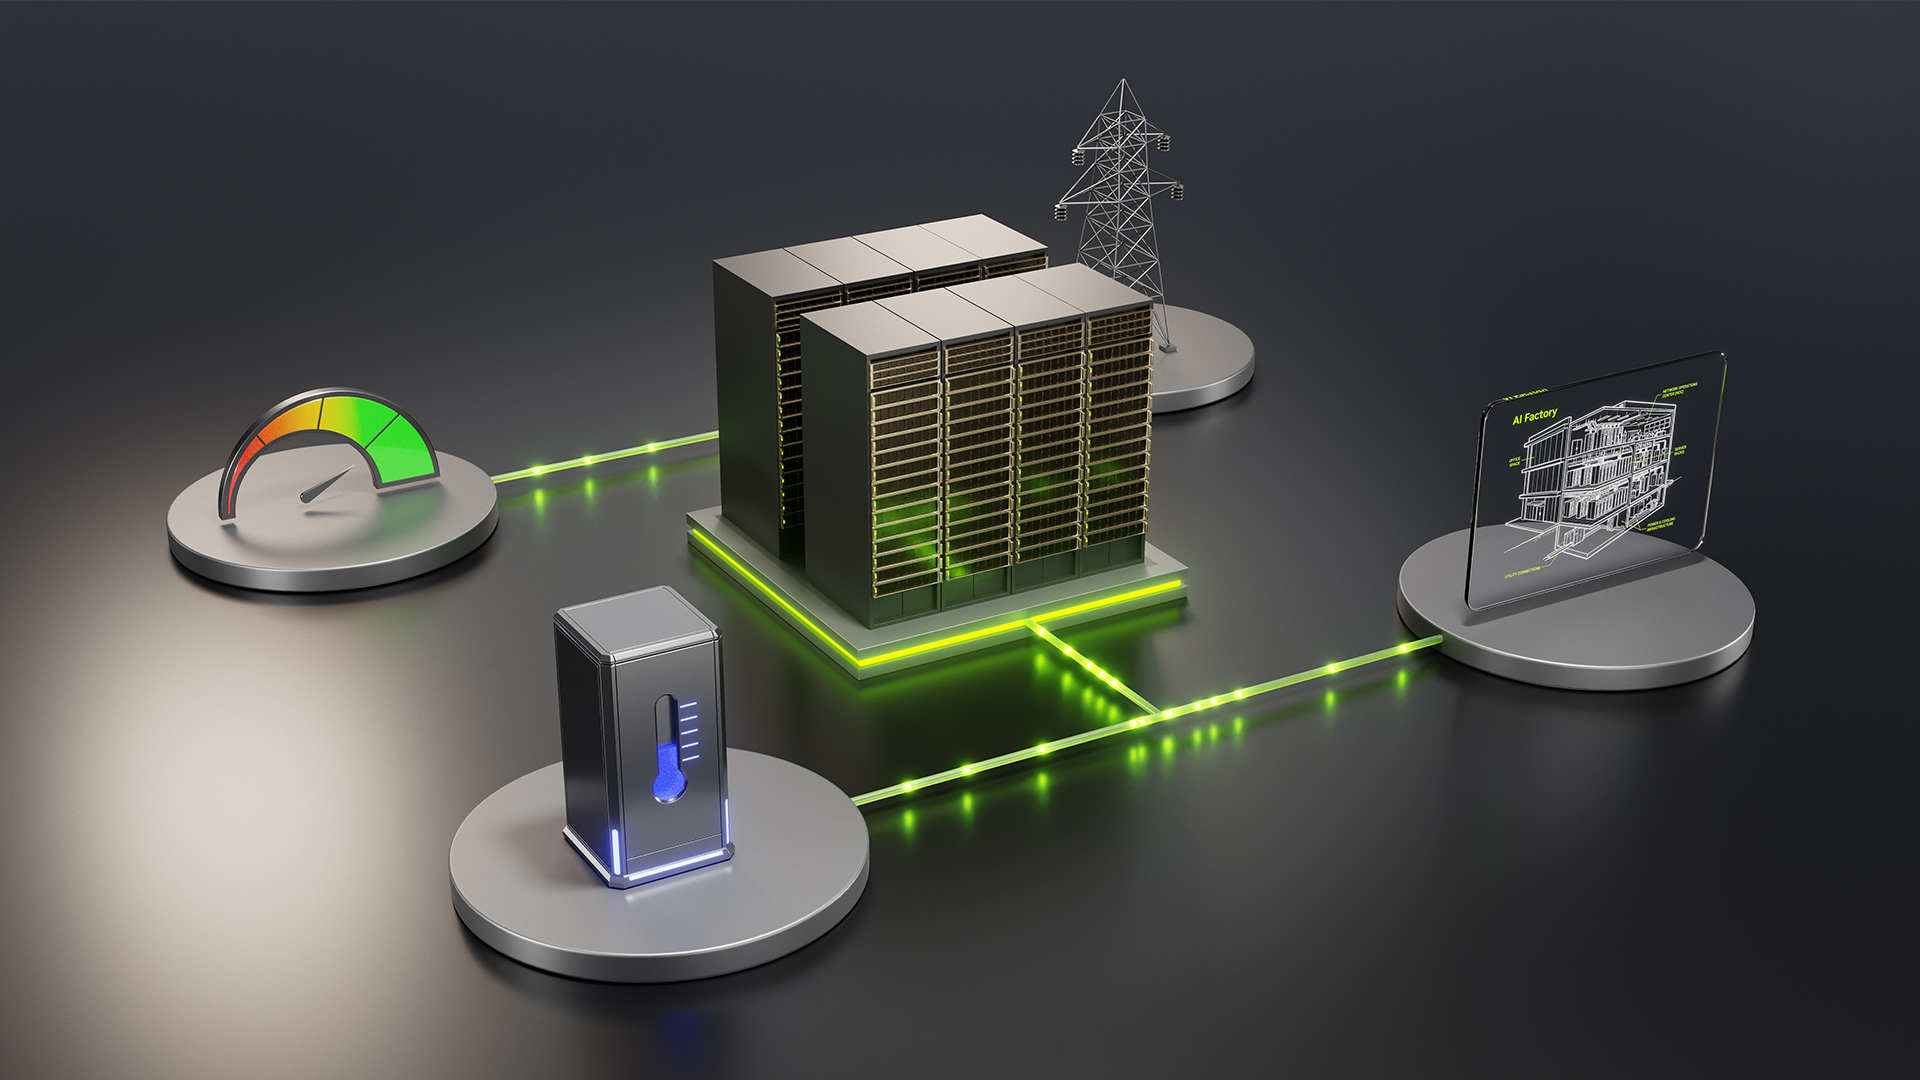
Emerald AI’s Conductor took Silicon Valley Power demand signals across thousands of NVIDIA GPUs—200+ events, power dropping on cue—showing AI factories as controllable grid citizens.

At AI Infra Summit, NVIDIA’s Ian Buck highlighted Vera Rubin, DSX, Emerald AI flex load with Silicon Valley Power, Lambda’s 23% perf-per-watt gain, and partner deals from Annapurna to d-Matrix.

NVIDIA details Groq 3 LPX deterministic execution on Vera Rubin—cycle-exact scheduling across 256 LPUs, plus PEP/CPS tricks cutting voltage droop over 60% for interactive inference efficiency.

NVIDIA’s NVLink 6 stack pairs silicon FEC/retry, credit-based flow control, NMX contain-and-drain, and Dynamo Shadow Engine Recovery that restores inference in 7.3s versus 283s cold start on B200.

NVIDIA FLARE 2.9 adds Slurm beside Docker and Kubernetes so federated-learning sites keep local GPUs, secrets, and schedulers without forcing one cluster standard.

At Dreamforce, Salesforce unveiled Koa — a Nemotron-based reasoning model post-trained for sales and support without touching customer data — and aimed it at Claude and ChatGPT token bills.

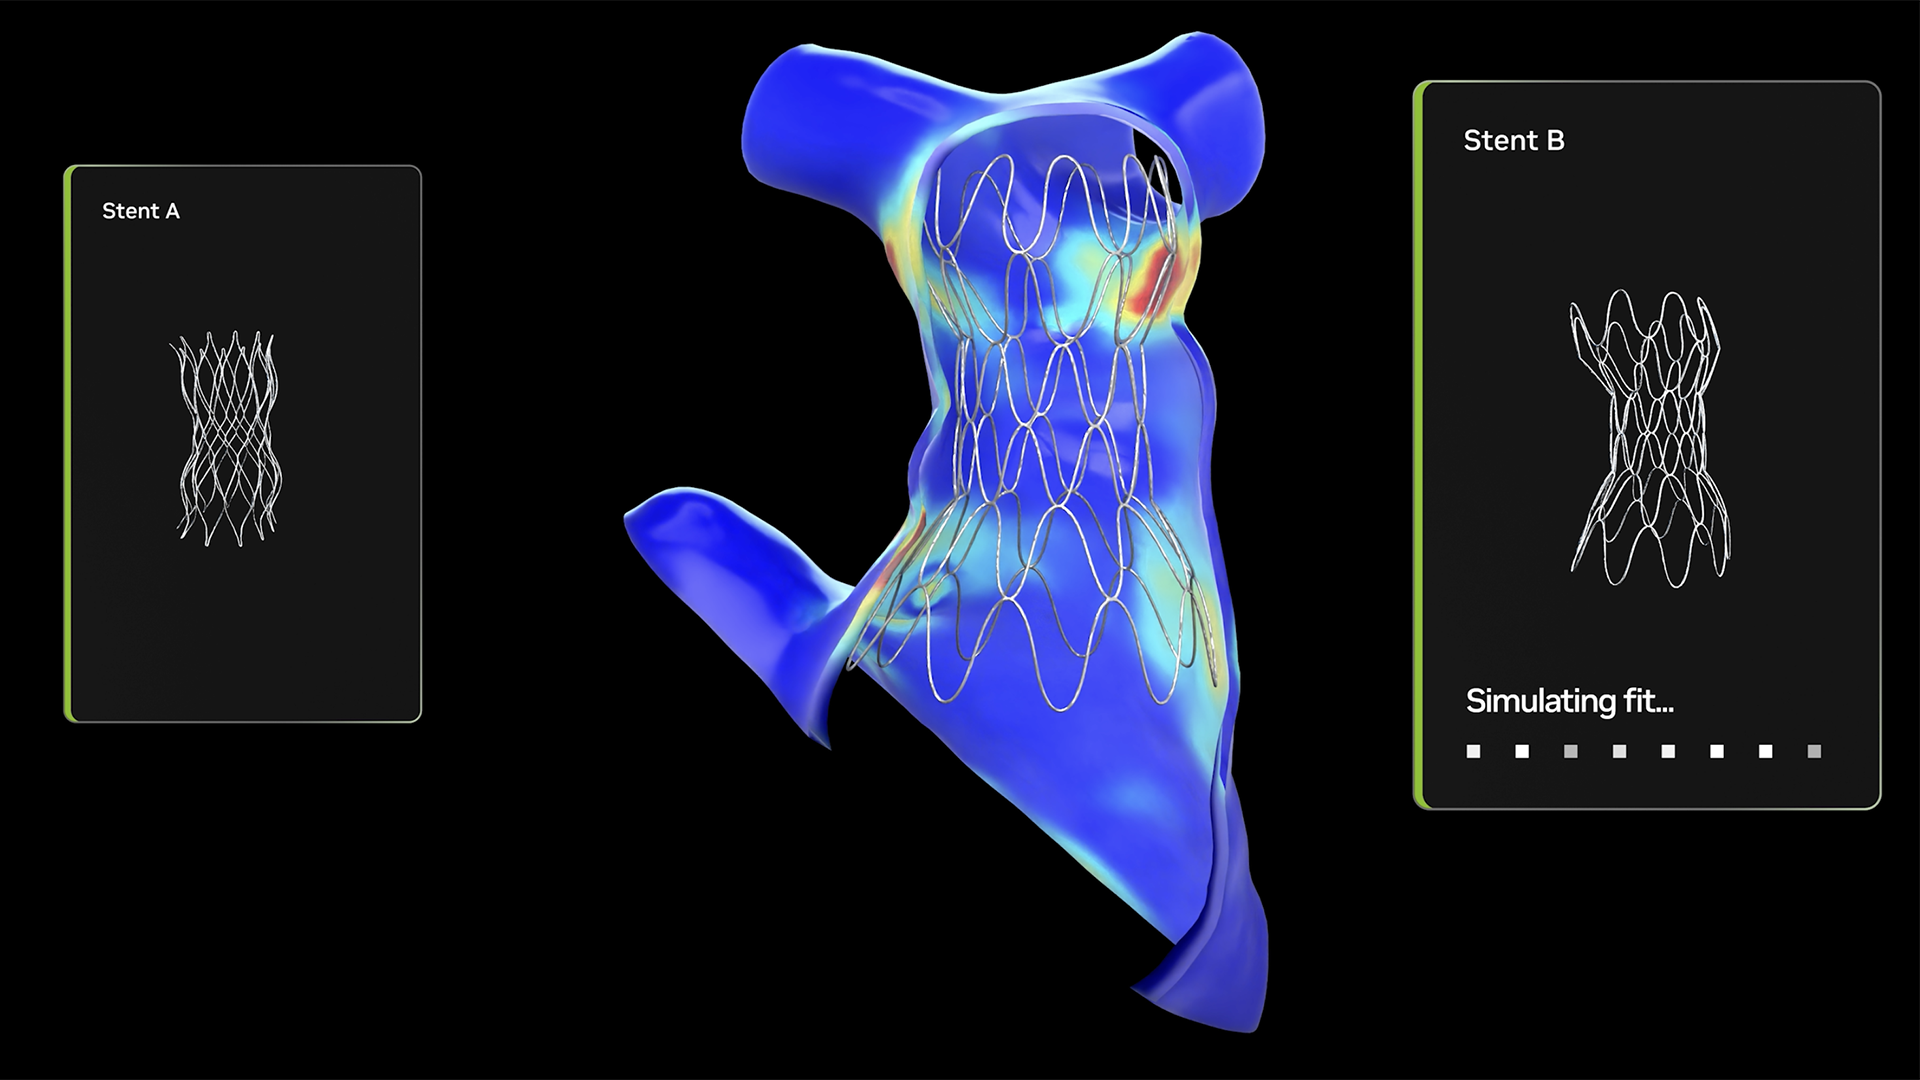
CHOP turned hours of pediatric heart modeling into seconds with MONAI — and is pushing GPU physics toward same-day device-fit decisions for congenital heart disease.

On speakerphone at All-In, Huang told Trump “you’re right” — they won’t let an AI slowdown happen — as the president branded the scare a hoax.

Onstage at the All-In Summit, Jensen Huang put President Trump on speakerphone — and Trump called AI slowdown fears a “hoax” while promising robots won’t take over.

NVIDIA says Transformer Engine plus JAX lifted DeepSeek-V3 MoE training from 103 to 1,068 TFLOPS/GPU on GB200 — a 10.4× jump — while keeping dropless routing.

Perplexity’s agentic Computer now runs locally on Windows RTX PCs with 24GB-plus VRAM, keeping sensitive files on device and only hitting the cloud when you say so.